Data engineer resume examples & writing guide for 2026

Three data engineer resumes at entry, mid and staff level, each rendered in a real template and annotated line by line. Every one gives the volume, the freshness target and the cost a pipeline runs at, which is what a platform lead checks first.

By the Resumi editorial teamUpdated 9 min read

Showing the mid-level example

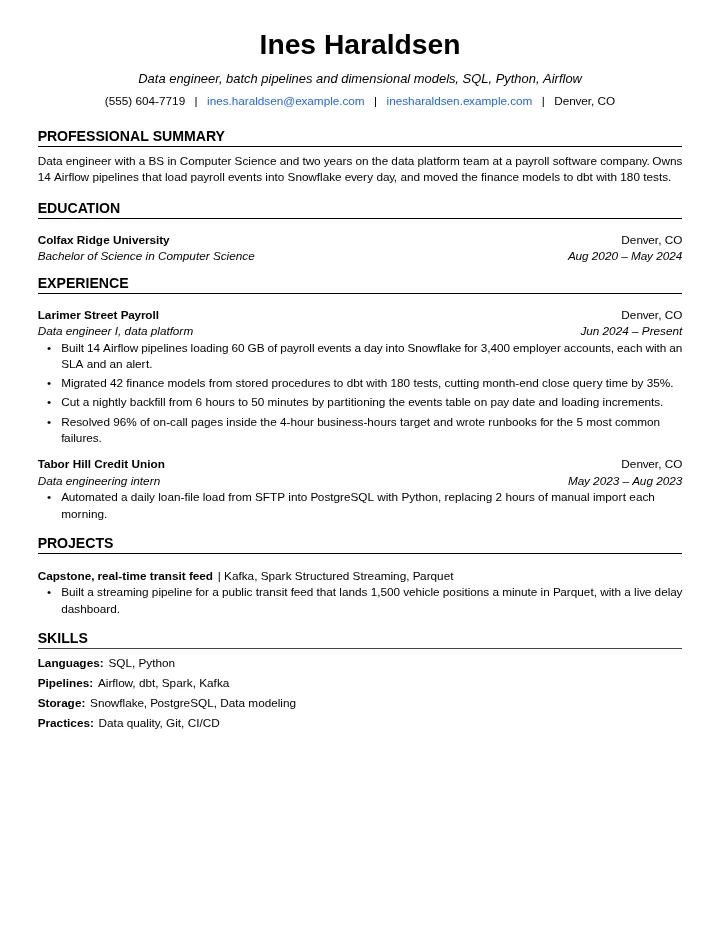
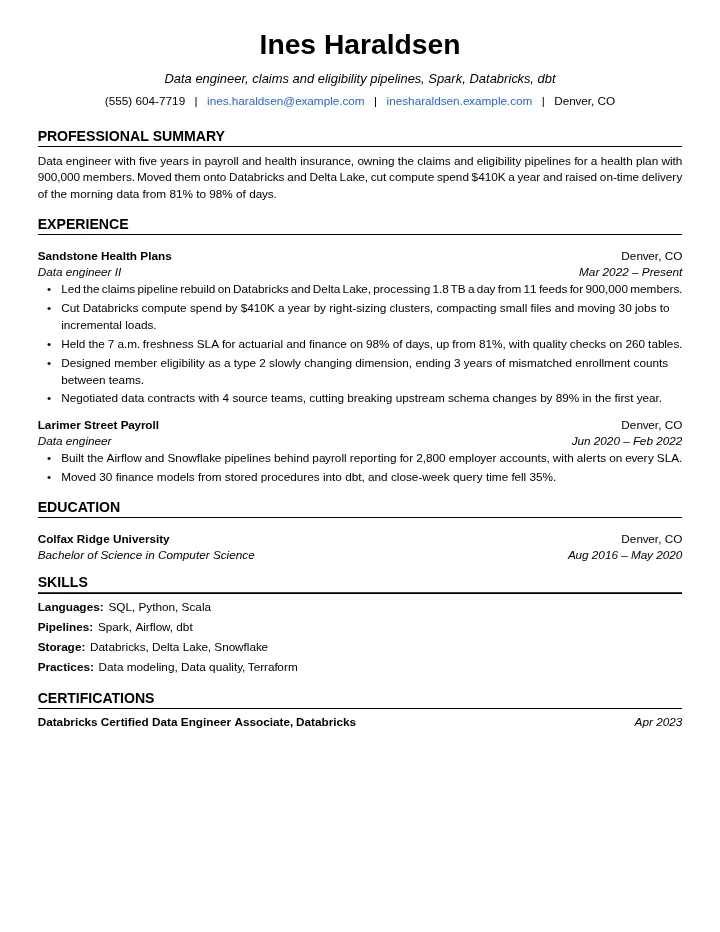
Data engineer resume example, mid level, rendered in The Jake's template
Strength: Excellent

Written by the Resumi editorial team for a fictional candidate. Role facts come from O*NET and the U.S. Bureau of Labor Statistics.

Strength band is Resumi’s optimization score, not a ranking any employer sees.

What makes this resume work

Each marker on the page has a note here. Press a marker to jump to its note.

  1. 1

    Domain and platform together

    Claims and eligibility pipelines on Spark, Databricks and dbt. A health plan hiring manager sees the domain and the platform in one line, which is most of the fit decision for this level.

  2. 2

    Terabytes, feeds and members

    One point eight terabytes a day from eleven feeds for nine hundred thousand members. Volume, source count and population together size the job in a way no adjective can, and each one is checkable.

  3. 3

    Compute spend in dollars

    Four hundred ten thousand dollars a year saved through cluster sizing, file compaction and incremental loads. Cost is now written into many data engineering job descriptions, and the method is named.

  4. 4

    A dimension that ended a dispute

    Eligibility modeled as a type 2 slowly changing dimension, ending three years of mismatched enrollment counts. It shows data modeling skill in the language warehouse teams use and ties it to an outcome.

  5. 5

    Contracts with source teams

    Four source teams signed up and breaking schema changes fell by eighty-nine percent. Mid-level engineers are expected to fix problems upstream rather than patch them, and this line shows exactly that.

  6. 6

    One vendor certification, matched

    The Databricks associate credential matches the platform in every bullet above it. A single certification tied to the stack reads as proof, while a list of unrelated ones reads as padding.

Build your data engineer resume

Free to start · no card

01The example, in full

The resume shown above, as text you can search and copy.

Ines Haraldsen

Data engineer, claims and eligibility pipelines, Spark, Databricks, dbt

Denver, COines.haraldsen@example.com(555) 604-7719inesharaldsen.example.com

Summary

Data engineer with five years in payroll and health insurance, owning the claims and eligibility pipelines for a health plan with 900,000 members. Moved them onto Databricks and Delta Lake, cut compute spend $410K a year and raised on-time delivery of the morning data from 81% to 98% of days.

Experience

Data engineer II

Mar 2022 – Present

Sandstone Health Plans · Denver, CO

  • Led the claims pipeline rebuild on Databricks and Delta Lake, processing 1.8 TB a day from 11 feeds for 900,000 members.
  • Cut Databricks compute spend by $410K a year by right-sizing clusters, compacting small files and moving 30 jobs to incremental loads.
  • Held the 7 a.m. freshness SLA for actuarial and finance on 98% of days, up from 81%, with quality checks on 260 tables.
  • Designed member eligibility as a type 2 slowly changing dimension, ending 3 years of mismatched enrollment counts between teams.
  • Negotiated data contracts with 4 source teams, cutting breaking upstream schema changes by 89% in the first year.

Data engineer

Jun 2020 – Feb 2022

Larimer Street Payroll · Denver, CO

  • Built the Airflow and Snowflake pipelines behind payroll reporting for 2,800 employer accounts, with alerts on every SLA.
  • Moved 30 finance models from stored procedures into dbt, and close-week query time fell 35%.

Education

Bachelor of Science in Computer Science

Aug 2016 – May 2020

Colfax Ridge University · Denver, CO

Skills

Languages
SQL, Python, Scala
Pipelines
Spark, Airflow, dbt
Storage
Databricks, Delta Lake, Snowflake
Practices
Data modeling, Data quality, Terraform

Certifications

Databricks Certified Data Engineer Associate

Apr 2023

Databricks

02Market snapshot

Median pay
$139,500 median annual pay for database architects, the occupation O*NET files data engineers under
Typical education
Bachelor's degree in computer and information technology or a related field
Job outlook
+9% projected growth for database architects, 2025–35, and about 7,300 openings a year with administrators
Common credentials
No license. 62 certifications listed, most tied to one vendor's product

Sources: BLS OES (May 2025) · BLS OOH (2025) · CareerOneStop (2026)

03The same resume at three levels

The tinted row is the level shown above.

  • Entry-level

    0–2 years

    The degree and a working streaming project frame two years of batch work. Each pipeline claim carries a volume, an account count, a runtime or an on-call target, and the dbt migration comes with its test count. The internship keeps one automation line with the time it saved.

    Typical titles: Data engineer I, Data engineer, Analytics engineer

  • Mid-level

    3–6 years

    Ownership of a domain replaces a set of jobs. The bullets carry a daily volume, a compute saving in dollars, a freshness SLA with its before and after, a dimension design that settled a dispute and contracts with source teams. The payroll years keep two lines and a vendor certification appears.

    Typical titles: Data engineer II, Senior data engineer, Data platform engineer

  • Senior

    7+ years

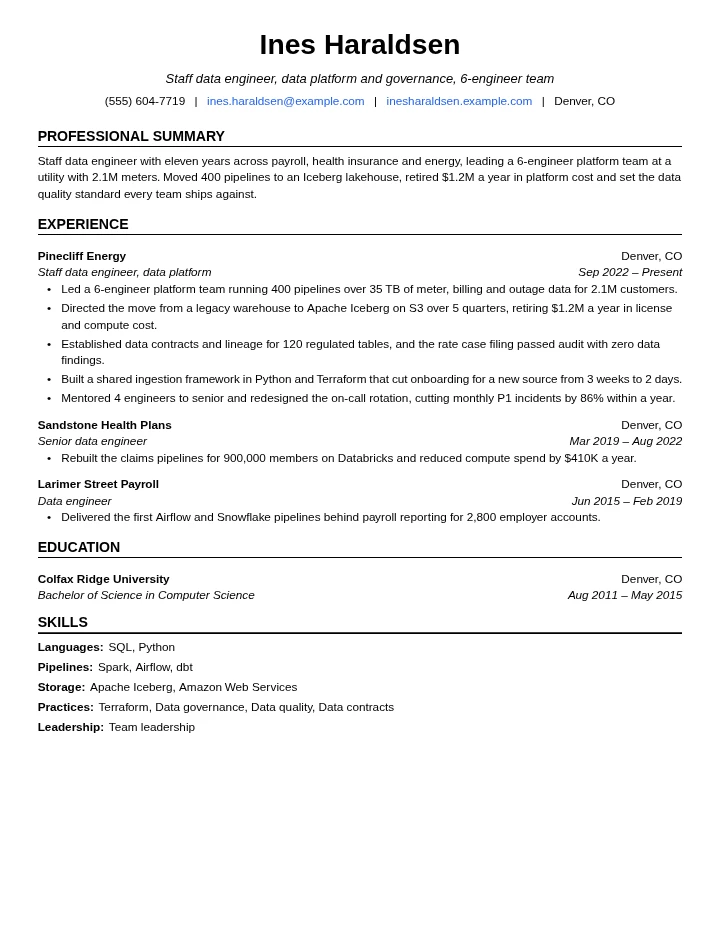
    Scope moves from pipelines to a platform: a team of six, four hundred pipelines, a multi-quarter lakehouse migration priced in retired cost, governance that survived a regulatory audit and an on-call redesign measured in incidents. Two earlier employers shrink to one line each.

    Typical titles: Staff data engineer, Lead data platform engineer, Senior staff data engineer

04Summary

Weak

Detail-oriented data engineer with strong experience in big data technologies, building robust and scalable ETL pipelines to support business intelligence needs.

Strong

Data engineer with five years in payroll and health insurance, owning the claims and eligibility pipelines for a health plan with 900,000 members. Moved them onto Databricks and Delta Lake, cut compute spend $410K a year and raised on-time delivery of the morning data from 81% to 98% of days.

The strong version names the domain, the member count, the platform, a dollar saving and a reliability number with its baseline. A platform lead can ask how the clusters were sized or what broke the SLA before. The weak one says big data and scalable and proves neither.

05Bullets

Weak

  • Responsible for maintaining ETL pipelines and ensuring data is delivered to stakeholders on time.

Strong

  • Held the 7 a.m. freshness SLA for actuarial and finance on 98% of days, up from 81%, with quality checks on 260 tables.

It names the consumers, the target time, the rate before and after, and the checks that made the change stick. Freshness against an agreed time is how data platform teams are judged, and a hiring manager can test every part of it. The weak bullet describes a duty and promises timeliness without a number.

06Skills and keywords

Languages

  • SQL (in the example)
  • Python (in the example)
  • Scala (in the example)
  • Java

Pipelines

  • Spark (in the example)
  • Airflow (in the example)
  • dbt (in the example)
  • Kafka
  • Fivetran

Storage

  • Databricks (in the example)
  • Delta Lake (in the example)
  • Snowflake (in the example)
  • Apache Iceberg
  • BigQuery
  • Amazon Redshift

Practices

  • Data modeling (in the example)
  • Data quality (in the example)
  • Data contracts (in the example)
  • Terraform (in the example)
  • Data governance
  • Kubernetes

Credentials

  • Databricks Certified Data Engineer Associate (in the example)
  • Google Professional Data Engineer
  • AWS Certified Data Engineer - Associate
  • Certified Data Management Professional (CDMP)

Filled chips appear in the example above.

Paste a job description and Resumi shows which of these your resume already covers.

Build your data engineer resume

07Mistakes to avoid

  1. Pipelines with no volume or freshness target

    Fix: A pipeline without a size and a deadline could be a cron job on a laptop. Give the daily volume, the number of sources and consumers, the time the data must land and the share of days it did. Platform leads read those numbers before anything else.

  2. Every bullet opens with responsible for

    Fix: Practitioners who hire data engineers say a list of responsibilities is the quickest way to the reject pile. Start with the change you made: built, migrated, cut, held. Then give what moved, whether runtime, cost, freshness or incidents, and by how much.

  3. On-call and reliability left off

    Fix: Postings at every level name on-call, SLAs, observability and incident response, yet most resumes skip them. Say what you were paged for, how fast you resolved it, what you automated afterwards and how the incident count changed. It reads as ownership.

  4. Cloud spend never mentioned

    Fix: Cost now sits in the job description at many employers. If you right-sized clusters, compacted small files, moved jobs to incremental loads or retired a license, put the annual dollar figure on it. Few candidates do, so it stands out.

  5. A dated tool leading the skills line

    Fix: Hiring managers read the first tools on the line as your current stack. Lead with what you would defend in a live exercise today. Keep an older warehouse or ETL tool only when the posting names it, and put it last rather than first.

08Format and template

One column and one page, in the order summary, experience, projects, education, skills. Put the platform and the orchestration tool in the headline, because recruiters match those first. Keep volumes, SLAs and dollar figures in the bullets as text, not inside a diagram, and link a repository with a working project rather than describing it. This example uses The Jake's template. Standard, Executive Classic and Warm Classic hold the same content in one column.

Shown above: The Jake's

  • Standard template
    StandardFree
  • Executive Classic template
    Executive Classic
  • Warm Classic template
    Warm Classic

09Questions data engineers ask

Are Databricks or Google data engineer certifications worth it?

Sometimes, when they match the stack you are applying to. BLS notes that employers may require certification in the products they use, and CareerOneStop lists 62 certifications from 23 organizations for the occupation, most of them tied to one vendor. The Databricks, Google Cloud and AWS data engineer exams are common. List the one that matches the posting, and never above a pipeline you actually shipped.

Do I have to start as a data analyst before data engineering?

No. Entry postings ask for SQL, Python, one orchestration tool and a pipeline you owned end to end, often with seniors making the architecture calls. A project with a working output, a repository, tests and a short architecture note does more than an analyst title. If you did start in analytics, move the pipeline work to the top of each role.

AWS, GCP or Azure: which cloud should my resume show?

The one you used most deeply, named plainly. Postings usually list the three as interchangeable, and in 2025 postings for database architects AWS and Azure each appeared in 20 percent. Depth in one reads better than a list of three. Name the services you ran pipelines on, such as object storage, a managed warehouse or a managed orchestrator, and the volume they carried.

How do I show analytics engineering versus platform work?

By the verbs and the users. Analytics engineering bullets are about dbt models, tests, metric definitions and the analysts who rely on them. Platform bullets are about frameworks, infrastructure as code, CI/CD, cost and the engineers who build on your platform. Decide which job you want, lead each role with that kind of work and keep the other to a line.

How do I move from data engineering into platform or infrastructure work?

Show the infrastructure you already touch. Terraform for your own pipelines, Kubernetes jobs, CI/CD you set up, on-call you carried and costs you cut all count. Put them in the first bullets of your current role. A certification alone rarely gets past the screen for these roles without one of those lines behind it. Ask to own a piece of your team's infrastructure before you apply.

Free to start

Build your data engineer resume

No card, no trial that turns into a charge.

Sign up free