Data scientist resume examples & writing guide for 2026

Three data scientist resumes at entry, mid and staff level, each rendered in a real template and annotated line by line. Every one leads with a model or an experiment, the metric it moved and the decision it changed.

By the Resumi editorial teamUpdated 9 min read

Showing the mid-level example

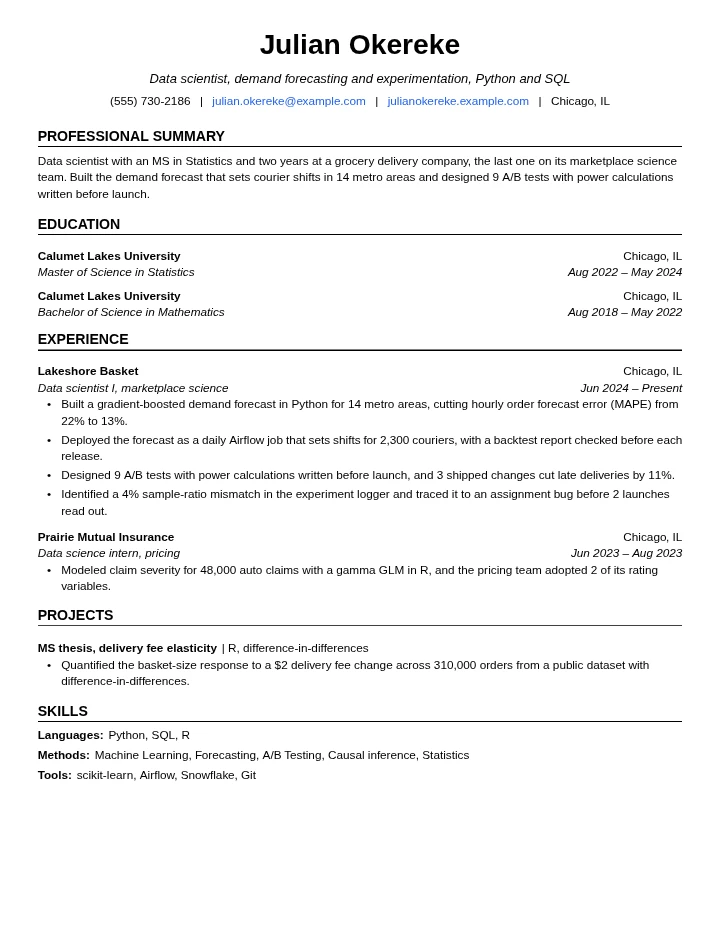
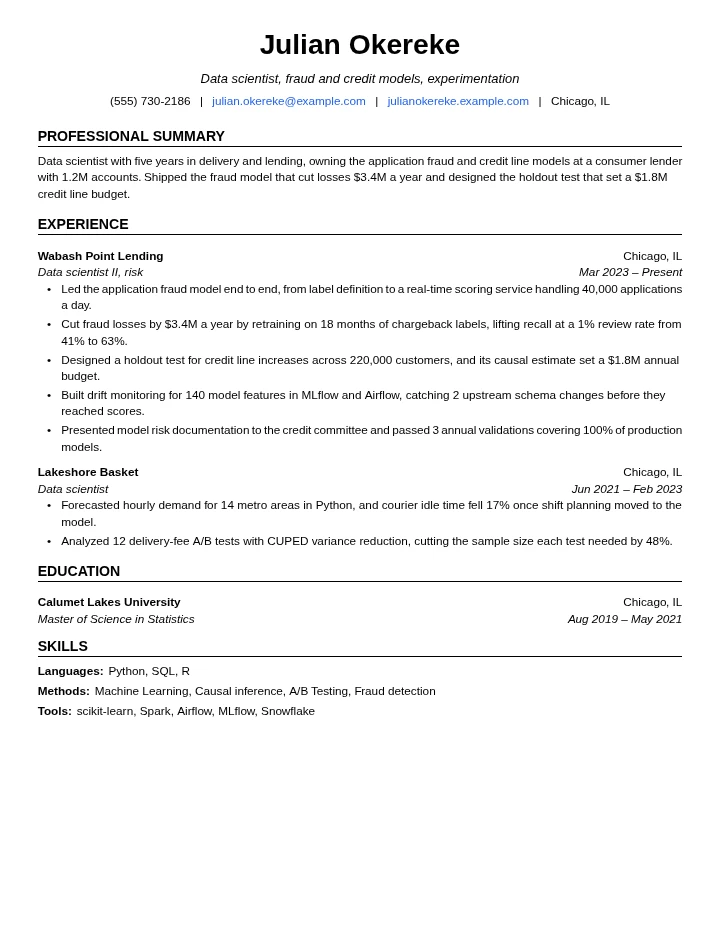
Data scientist resume example, mid level, rendered in The Jake's template
Strength: Excellent

Written by the Resumi editorial team for a fictional candidate. Role facts come from O*NET and the U.S. Bureau of Labor Statistics.

Strength band is Resumi’s optimization score, not a ranking any employer sees.

What makes this resume work

Each marker on the page has a note here. Press a marker to jump to its note.

  1. 1

    Model families in the headline

    Fraud and credit models, plus experimentation. Lending teams hire for the model family they run, and a headline that names it gets the resume routed to the right hiring manager on the first pass.

  2. 2

    End to end, down to serving

    From label definition to a real-time service scoring forty thousand applications a day. Owning the whole path is the mid-level expectation, and the daily volume shows the model carries real traffic.

  3. 3

    Recall at a fixed review rate

    Forty-one percent to sixty-three at a one percent review rate, then the dollars. Fraud teams judge models at the operating point their review queue can handle, and quoting it shows the candidate knows that.

  4. 4

    A causal estimate set a budget

    A holdout across two hundred twenty thousand customers produced the number finance used for a credit line budget. It is the clearest line on the page separating data science from reporting.

  5. 5

    Monitoring that caught something

    Drift checks on one hundred forty features caught two upstream schema changes before they reached scores. Saying what the monitoring caught is what makes a monitoring claim believable.

  6. 6

    Model risk validations passed

    Documentation presented to the credit committee and three annual validations passed. Regulated lenders need scientists who can defend a model to a review body, so this line matters as much as accuracy does.

Build your data scientist resume

Free to start · no card

01The example, in full

The resume shown above, as text you can search and copy.

Julian Okereke

Data scientist, fraud and credit models, experimentation

Chicago, ILjulian.okereke@example.com(555) 730-2186julianokereke.example.com

Summary

Data scientist with five years in delivery and lending, owning the application fraud and credit line models at a consumer lender with 1.2M accounts. Shipped the fraud model that cut losses $3.4M a year and designed the holdout test that set a $1.8M credit line budget.

Experience

Data scientist II, risk

Mar 2023 – Present

Wabash Point Lending · Chicago, IL

  • Led the application fraud model end to end, from label definition to a real-time scoring service handling 40,000 applications a day.
  • Cut fraud losses by $3.4M a year by retraining on 18 months of chargeback labels, lifting recall at a 1% review rate from 41% to 63%.
  • Designed a holdout test for credit line increases across 220,000 customers, and its causal estimate set a $1.8M annual budget.
  • Built drift monitoring for 140 model features in MLflow and Airflow, catching 2 upstream schema changes before they reached scores.
  • Presented model risk documentation to the credit committee and passed 3 annual validations covering 100% of production models.

Data scientist

Jun 2021 – Feb 2023

Lakeshore Basket · Chicago, IL

  • Forecasted hourly demand for 14 metro areas in Python, and courier idle time fell 17% once shift planning moved to the model.
  • Analyzed 12 delivery-fee A/B tests with CUPED variance reduction, cutting the sample size each test needed by 48%.

Education

Master of Science in Statistics

Aug 2019 – May 2021

Calumet Lakes University · Chicago, IL

Skills

Languages
Python, SQL, R
Methods
Machine Learning, Causal inference, A/B Testing, Fraud detection
Tools
scikit-learn, Spark, Airflow, MLflow, Snowflake

02Market snapshot

Median pay
$120,230 median annual pay, with the top 10 percent above $199,130
Typical education
Bachelor's degree to enter, though some employers require or prefer a master's or doctorate
Job outlook
About 24,800 openings a year, and 35% projected growth for 2025–35, much faster than average
Common credentials
No state license. 18 optional certifications listed, among them Google's machine learning engineer exam

Sources: BLS OES (May 2025) · BLS OOH (2025) · CareerOneStop (2026)

03The same resume at three levels

The tinted row is the level shown above.

  • Entry-level

    0–2 years

    The degree and the thesis come first, then one forecast followed from build to production and a test program with its power calculations written down. The internship keeps one modeling line with the claim count. The skills line splits languages, methods and tools the way postings list them.

    Typical titles: Data scientist I, Data scientist, Product data scientist

  • Mid-level

    3–6 years

    Ownership of two models replaces a single forecast. The bullets carry the operating point a fraud team judges by, a causal estimate that set a budget, drift monitoring and a validation record. The delivery years keep two lines, each with the method and the result.

    Typical titles: Data scientist II, Senior data scientist, Applied scientist

  • Senior

    7+ years

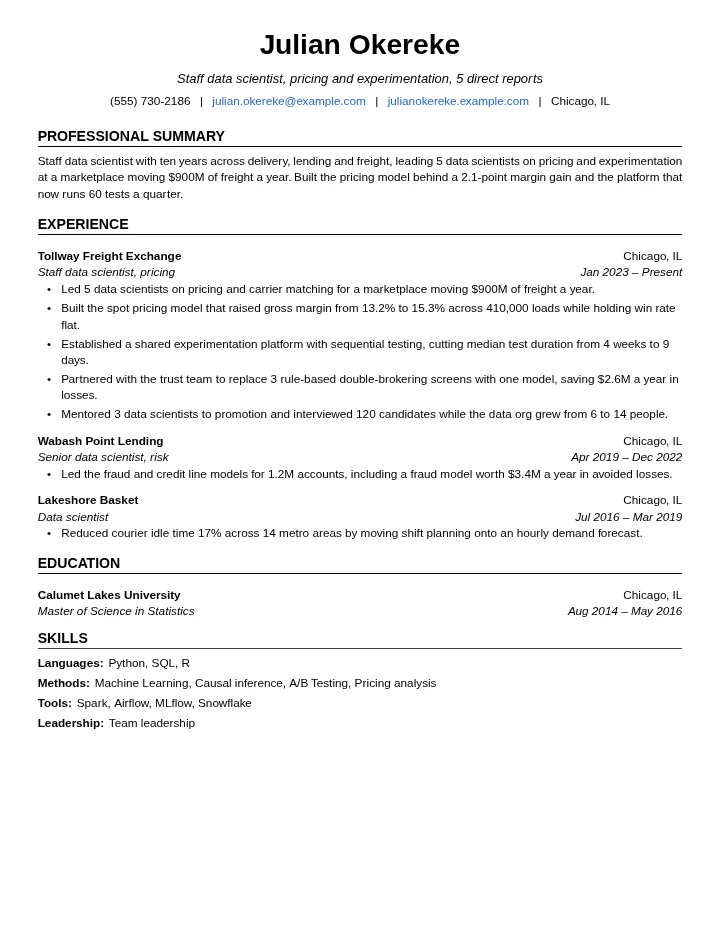
    Scope moves from models to a team and a platform: five direct reports, a pricing model measured in margin points, an experimentation platform measured in test duration and a fraud model replacing three rule sets. The lending and delivery years shrink to one line each.

    Typical titles: Staff data scientist, Lead data scientist, Principal data scientist

04Summary

Weak

Results-driven data scientist passionate about leveraging machine learning and big data to deliver actionable insights and drive business value across the organization.

Strong

Data scientist with five years in delivery and lending, owning the application fraud and credit line models at a consumer lender with 1.2M accounts. Shipped the fraud model that cut losses $3.4M a year and designed the holdout test that set a $1.8M credit line budget.

The strong version names two models, the account base they run on, a loss figure and a budget decision. A hiring manager can ask how the fraud labels were built or how the holdout was sized. The weak one lists buzzwords an analyst, an engineer or a scientist could claim.

05Bullets

Weak

  • Built machine learning models in Python to predict fraud and improve business outcomes for the risk team.

Strong

  • Cut fraud losses by $3.4M a year by retraining on 18 months of chargeback labels, lifting recall at a 1% review rate from 41% to 63%.

It gives the label source, the operating point and the metric at that point, then the money. Recall at a fixed review rate is how fraud teams judge a model, because the review queue has a fixed number of people. The weak bullet names a language and an intention and nothing a reviewer could check.

06Skills and keywords

Languages

  • Python (in the example)
  • SQL (in the example)
  • R (in the example)

Methods

  • Machine Learning (in the example)
  • Causal inference (in the example)
  • A/B Testing (in the example)
  • Fraud detection (in the example)
  • Statistics (in the example)
  • Deep Learning
  • Natural Language Processing

Tools

  • scikit-learn (in the example)
  • Spark (in the example)
  • Airflow (in the example)
  • MLflow (in the example)
  • Snowflake (in the example)
  • PyTorch
  • TensorFlow
  • Databricks

Credentials

  • Google Professional Machine Learning Engineer
  • Certified Analytics Professional (CAP)
  • Graduate Statistician (GStat)

Filled chips appear in the example above.

Paste a job description and Resumi shows which of these your resume already covers.

Build your data scientist resume

07Mistakes to avoid

  1. A model named with no decision attached

    Fix: Hiring managers at large employers reject lines like built a forecasting model in Python as too vague. Name the method, the metric it moved and the decision that changed because of it: a shift plan, a credit budget, a price.

  2. Offline accuracy and nothing about production

    Fix: Postings at every level now ask for production modeling code. Say where the model runs, how much traffic it scores, how it is monitored and how often it is retrained. An AUC from a notebook tells a reviewer you can train, not that you can ship.

  3. Data science listed as a skill

    Fix: It is the job title, not a skill. Recruiters and hiring managers read the domain instead: fraud detection, pricing, forecasting, ranking. Put the domain in the skills line and in the first bullet, and cut the generic term entirely.

  4. Experiments counted but never designed

    Fix: Senior experimentation postings ask about power calculations, multiple comparisons and sequential testing. A count of tests says little. Write how one was sized, what guardrail metric it protected and what the readout changed, and you have answered half the interview.

  5. Teaching or finance years above the projects

    Fix: Career changers lose callbacks when two decades of earlier duties sit above the data work. Put the summary, then projects with real data and results, then the earlier career in two or three lines. Keep only what you can explain without notes.

08Format and template

One column and one page, in the order summary, experience, projects, education, skills. Keep the method and the metric inside each bullet and let the skills line repeat the tool names by kind, because a reviewer reads the first three bullets before the skills. Give the degree field its own line, since most postings name one. This example uses The Jake's template. Standard, Executive Classic and Warm Classic hold the same content in one column.

Shown above: The Jake's

  • Standard template
    StandardFree
  • Executive Classic template
    Executive Classic
  • Warm Classic template
    Warm Classic

09Questions data scientists ask

Do I need a master's or PhD to be hired as a data scientist?

Not always, but it helps more here than in analytics. BLS lists a bachelor's as the typical entry education and notes that some employers require or prefer a master's or doctorate. In O*NET's survey, 48 percent said a bachelor's is required and 44 percent a master's. Doctorates show up mostly in research-leaning and senior postings. Without a graduate degree, lead with production work and experiment design.

Can I call myself a data scientist if my work was mostly dashboards?

Use the title you held, then let the bullets show the work honestly. If the job was reporting, a data analyst resume will read better and interview better. If you built one real model or designed one test properly, lead with it and give it the most space. Reviewers compare the title against the bullets, and a mismatch costs more than a modest title.

How do I show that a model reached production?

Name the system it runs in and the volume it scores: a daily batch job setting courier shifts, a real-time service scoring applications. Add how it is monitored and what the monitoring caught. Give one online result next to the offline metric. Postings ask for production modeling code at every level now, so a model that never left a notebook reads as coursework.

Which data science certifications are worth listing?

Most postings do not ask for one. CareerOneStop lists 18 certifications from 11 organizations, including Google's Professional Machine Learning Engineer. The American Statistical Association offers GStat and PStat accreditation, and INFORMS offers the Certified Analytics Professional. List one only if it matches the job, and never above a shipped model or a published result, which carry more weight with the people hiring.

How should a data scientist resume show LLM work?

Describe the evaluation, not the tool. Say what the model was asked to do, how you measured whether it did it, what it cost per call and what shipped. Several senior postings now ask candidates to evaluate LLM-based systems or decide where AI belongs in a workflow. A line that says you used ChatGPT tells a reviewer nothing about either.

Free to start

Build your data scientist resume

No card, no trial that turns into a charge.

Sign up free